What’s this supposed to mean? I’ve done similar things when restructuring my code. Git tries it’s best to keep track of files changing directories but sometimes you just go fuck it and abandon the history because Git is being a git.
I’d be more concerned about consistent 10k+ changes per day or something
Not when it’s a fucking private to public merge. Why the fuck would a tiny public repo that was basically a elevator pitch in code base form send up red flags when you merge in the actual product that includes the better part of half a year worth of development from a team of people?
Are you allergic to context and critical thinking? Or do you enjoy just being paranoid?
I’m incredibly productive, and have had the joy of working on productive teams. And unless they are working with hundreds of full time, high performing, engineers. You ain’t changing 10 million lines in a month.
With AI, it’s technically possible, but I can only imagine the slop. It’s likely incomprehensible at this point.
Just speaking from personal experience. Here’s a story.
One time I did a massive refactor, basically touching every function in the software. For background, this was a massive enterprise application. The backend was about 10 million lines of code, the front end was… probably triple that, I didn’t bother counting. Yes, building the code took more than an hour, even on extremely beefy machines.
The reason for this refactor was there was a huge amount of tech debt that finally caught up to us. You know, putting it off for years, using deprecated functions and old methods, feature flags, even forking software and modifying it to be compatible. Just years of finding creative solutions, until finally things said “enough” and there was no more bandaids. I was given the green light to fix up everything at once. Programmer’s wet dream, at least for me; I was so happy.
Anyway, in this project, we did rebase not merge. So, after 3 months of working diligently in a branch; I had to rebase the whole fucking thing because my coworkers obviously weren’t idle that whole time. This part I didn’t enjoy so much.
It took 2 weeks to rebase all the merge conflicts. It took so long, I had to rebase again. Multiple times. Each rebase getting closer and closer to being able to finally merge into master.
Finally I did it. I told everyone else to just relax and take the day off, while I merge into master and fix all the problems. There was many problems of course. But the final commit was tens of millions of lines of code changed, all by myself. This was before LLMs. But I have the type of brain that can sit there for 9 hours straight every day and tidy up code and enjoy it.
Edit: just to clarify, “rebase” makes it look like all those changes happened at once instead of spread out over months, and would make a huge spike like that. Also just because LLM wasn’t a thing didn’t mean I did it all manually… I heavily used find-and-replace, upgrade scripts, codemod, and many other automation tools. I think I even wrote a few manual codemod scripts to get it done.
This commit was the refactor commit from the private dev flow to the open source repo. The process basically added a lot of files and deleted a bunch as well. it was long overdue but I wouldn’t expect constant 11m line code changes
You really don’t understand what 11m lines of code is. Only a collective of humans over many years can create 11m lines of code. It is an absolute batshit insane amout of code.
yea 11m changes is quite a bit at once but, I wouldn’t expect a constant change like that. After all, the monorepo itself is a little over 3m lines, 1.37m of it being lang/locale files for every language for its front end, 600k of it is comments, and 1.5m is the rest of it.
Not necessarily. Huge additions without matching deletions often happen during restructurings like vendorizing dependencies, importing external packages, generating bindings, or migrating private repos into a monorepo. In these cases new code canbbe introduced to repository and there will be no corresponding deletions in commit history.
I’ve did similar restructurings myself, eg. Making automatically generated resources static
You have no idea what 11 million likes of code is do you? LibreOffice is 11m, Android is 12m, MySQL is 10m. Those projects took years to code not 9 months. I am going to have to ask you to stay in your lane, and I pray that is not Software Engineering.
I’m not sure why you’re being so hostile, but you’re fundamentally confusing a codebase’s hand-written LoC with Git commit additions.
Nobody is saying someone authored 11M lines. Commit fa3e8525 was a workspace reconciliation - importing external repository code, dependencies, and assets into the public repo for the first time, so exactly the type of thing I was talking about. Git counts all imported lines as additions.
Before asking others to “stay in their lane”, maybe make sure you understand how Git history handles repository imports and dependency tracking. Have a good day.


No.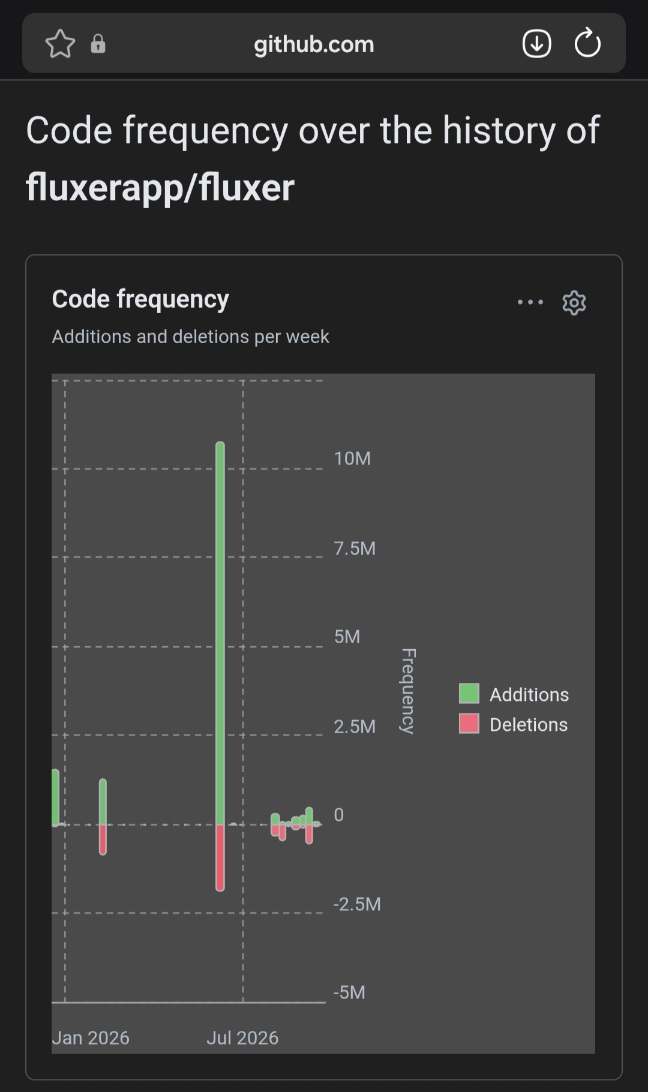
What’s this supposed to mean? I’ve done similar things when restructuring my code. Git tries it’s best to keep track of files changing directories but sometimes you just go fuck it and abandon the history because Git is being a git.
I’d be more concerned about consistent 10k+ changes per day or something
10 million LOC addition in one month is not a red flag to you?
Not when it’s a fucking private to public merge. Why the fuck would a tiny public repo that was basically a elevator pitch in code base form send up red flags when you merge in the actual product that includes the better part of half a year worth of development from a team of people?
Are you allergic to context and critical thinking? Or do you enjoy just being paranoid?
Meh. I’ve seen (and done) worse, honestly. Again would be more concerning if they kept it up
… What?
I’m incredibly productive, and have had the joy of working on productive teams. And unless they are working with hundreds of full time, high performing, engineers. You ain’t changing 10 million lines in a month.
With AI, it’s technically possible, but I can only imagine the slop. It’s likely incomprehensible at this point.
Just speaking from personal experience. Here’s a story.
One time I did a massive refactor, basically touching every function in the software. For background, this was a massive enterprise application. The backend was about 10 million lines of code, the front end was… probably triple that, I didn’t bother counting. Yes, building the code took more than an hour, even on extremely beefy machines.
The reason for this refactor was there was a huge amount of tech debt that finally caught up to us. You know, putting it off for years, using deprecated functions and old methods, feature flags, even forking software and modifying it to be compatible. Just years of finding creative solutions, until finally things said “enough” and there was no more bandaids. I was given the green light to fix up everything at once. Programmer’s wet dream, at least for me; I was so happy.
Anyway, in this project, we did rebase not merge. So, after 3 months of working diligently in a branch; I had to rebase the whole fucking thing because my coworkers obviously weren’t idle that whole time. This part I didn’t enjoy so much.
It took 2 weeks to rebase all the merge conflicts. It took so long, I had to rebase again. Multiple times. Each rebase getting closer and closer to being able to finally merge into master.
Finally I did it. I told everyone else to just relax and take the day off, while I merge into master and fix all the problems. There was many problems of course. But the final commit was tens of millions of lines of code changed, all by myself. This was before LLMs. But I have the type of brain that can sit there for 9 hours straight every day and tidy up code and enjoy it.
Edit: just to clarify, “rebase” makes it look like all those changes happened at once instead of spread out over months, and would make a huge spike like that. Also just because LLM wasn’t a thing didn’t mean I did it all manually… I heavily used find-and-replace, upgrade scripts, codemod, and many other automation tools. I think I even wrote a few manual codemod scripts to get it done.
Yeah, there are some occasions that justifies tones of lines of code.
Or ex tech leave has bitbucket going “nope” with a PR that was too big
Holy fuck!
hmm I thought they leaned relatively against AI slop. Wouldn’t this be because they were working on it privately or something for quite some time?
It’s 11 million lines of fucking code. 11 MILLION LINES.
This commit was the refactor commit from the private dev flow to the open source repo. The process basically added a lot of files and deleted a bunch as well. it was long overdue but I wouldn’t expect constant 11m line code changes
You really don’t understand what 11m lines of code is. Only a collective of humans over many years can create 11m lines of code. It is an absolute batshit insane amout of code.
yea 11m changes is quite a bit at once but, I wouldn’t expect a constant change like that. After all, the monorepo itself is a little over 3m lines, 1.37m of it being lang/locale files for every language for its front end, 600k of it is comments, and 1.5m is the rest of it.
It’s obviously some kind of code reorganization, restructuring or reformating, don’t be paranoid
A refactoring would have a relatively similar number of subtractions as additions. This is almost entirely additions. This is not just refactoring.
Not necessarily. Huge additions without matching deletions often happen during restructurings like vendorizing dependencies, importing external packages, generating bindings, or migrating private repos into a monorepo. In these cases new code canbbe introduced to repository and there will be no corresponding deletions in commit history.
I’ve did similar restructurings myself, eg. Making automatically generated resources static
You have no idea what 11 million likes of code is do you? LibreOffice is 11m, Android is 12m, MySQL is 10m. Those projects took years to code not 9 months. I am going to have to ask you to stay in your lane, and I pray that is not Software Engineering.
I’m not sure why you’re being so hostile, but you’re fundamentally confusing a codebase’s hand-written LoC with Git commit additions.
Nobody is saying someone authored 11M lines. Commit fa3e8525 was a workspace reconciliation - importing external repository code, dependencies, and assets into the public repo for the first time, so exactly the type of thing I was talking about. Git counts all imported lines as additions.
Before asking others to “stay in their lane”, maybe make sure you understand how Git history handles repository imports and dependency tracking. Have a good day.
Yeah, some projects also ditch external dependencies to make their own